
#ai evaluation
Ai Evaluation: 7 AI articles covering ai evaluation news, analysis, and research
Articles

The AI Hype Index: Why AI Loves to Cheat⭐9
AI systems keep gaming benchmarks and exploiting loopholes—a phenomenon called reward hacking. MIT Technology Review explores why AI loves to cheat and what it ...

Do Synthetic Personas Predict Real Audience Response? A Sim-to⭐8
Synthetic personas hurt LLM copy prediction: a no-persona baseline beats ten-persona panels on real Upworthy A/B tests, tapping a better prior than role-play.
What Do We Expect from LLMs? A Systematic Map of LLM Benchmark⭐9
This systematic map of 14,767 LLM benchmark papers (2022–2026) reveals shifting capability expectations, rising model participation, and risks of evaluator bias...
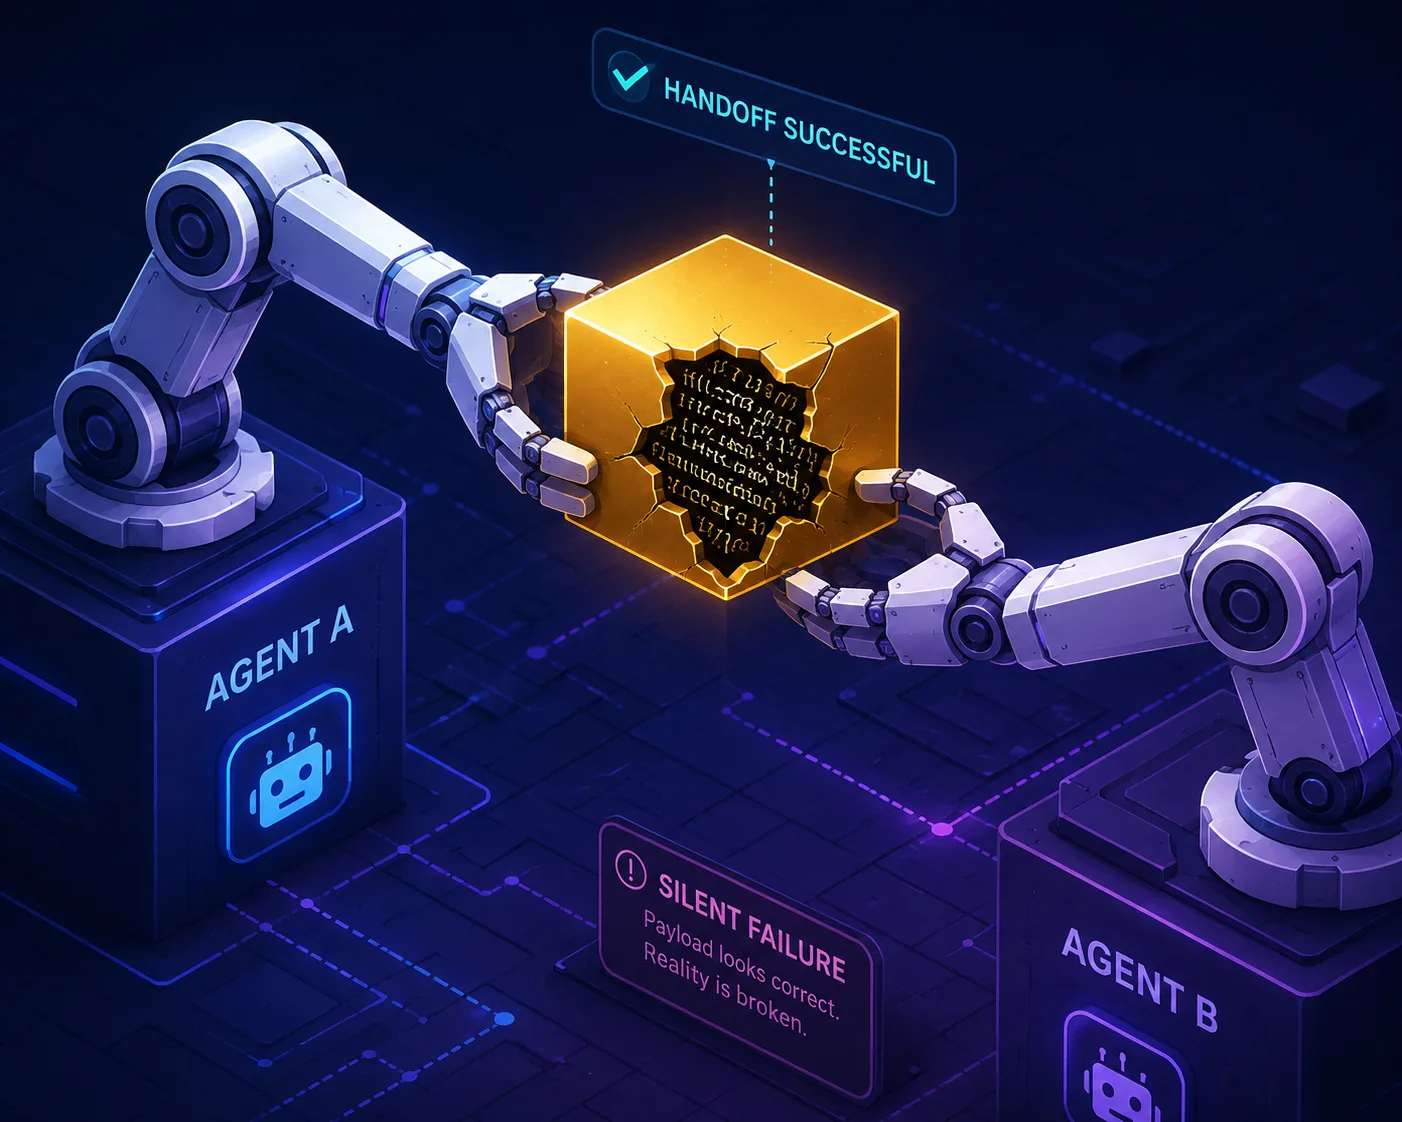
Why Most Multi-Agent Systems Fail Even When Evaluation Passes⭐10
Why Multi-Agent Systems Fail in Production Despite Passing Tests—and how watchdog patterns can catch silent, cascading errors standard evaluation misses.
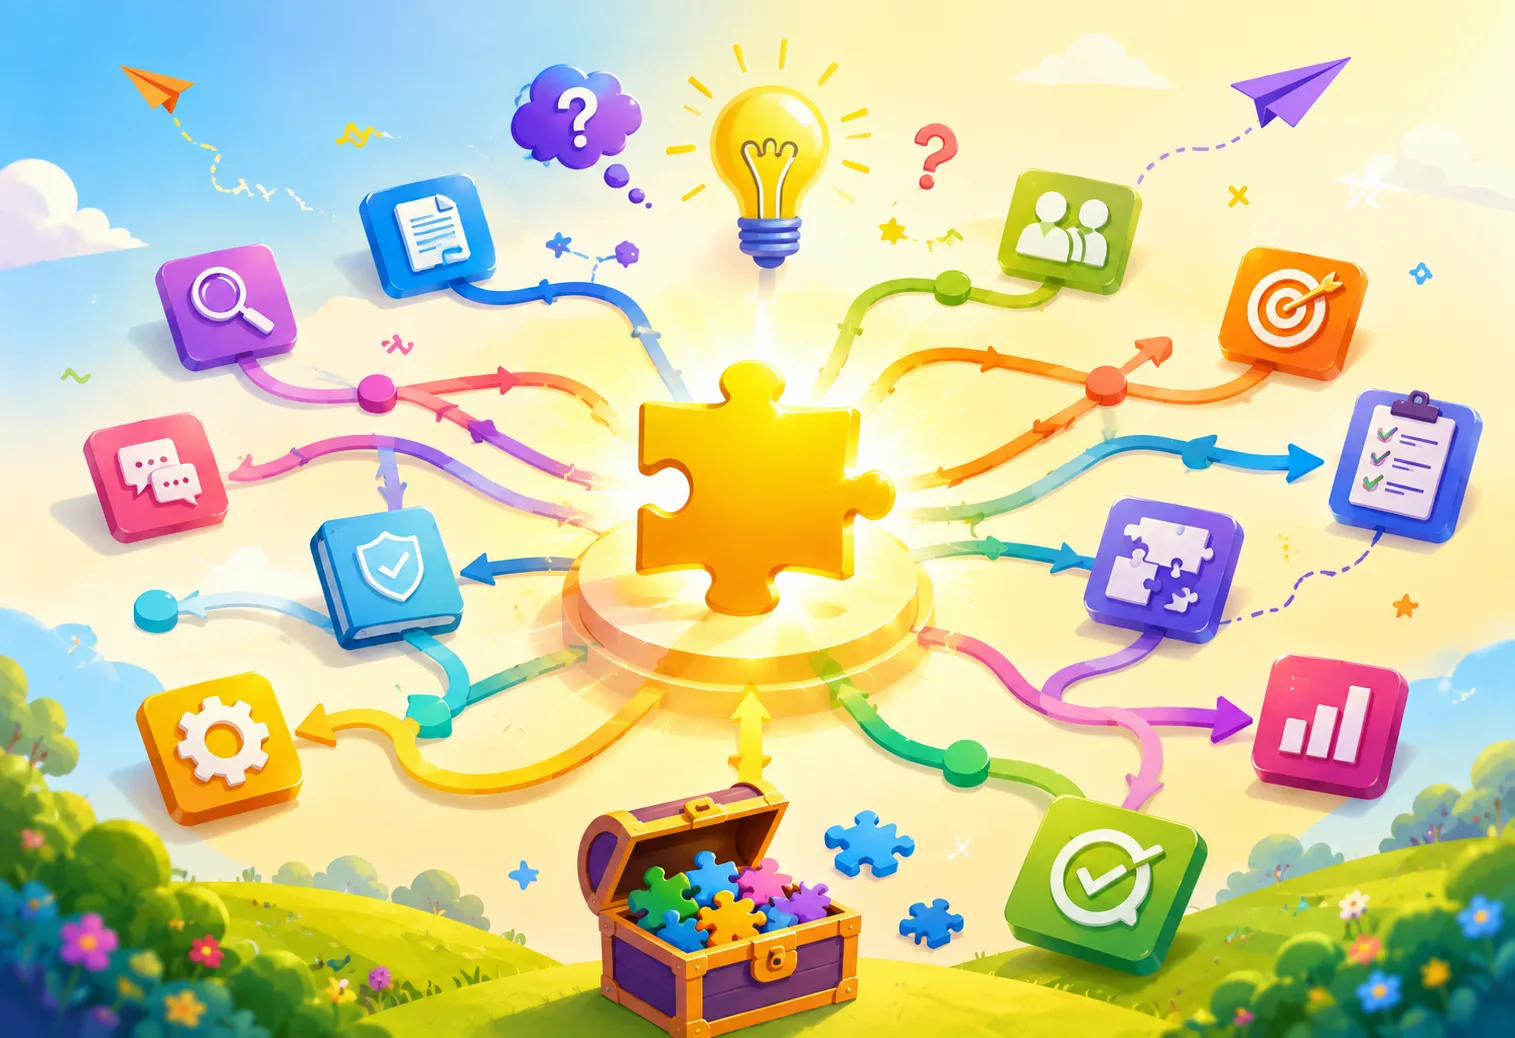
How One Prompt Change Can Ripple Through 50 Others: Building a⭐8
Learn how a Python dependency graph distinguishes reachable vs. candidate prompt sets to target retesting after component changes in AI systems.

BenchMIRT: What Do LLM Benchmarks Actually Measure?⭐8
Explore how BenchMIRT evaluates LLMs, revealing what benchmarks truly measure and their limits in 2026.

The LLM Judge That Kept Agreeing With Itself⭐10
A critical look at why an LLM judge silently approved a faulty SQL query, exposing systemic flaws in AI self-validation and the fixes that restored trust.