
#agentic ai
Agentic Ai: 188 AI articles covering agentic ai news, analysis, and research
Articles

AWS Launches Pizza Bot: An Open Source Inbox for Background AI Agents⭐9
AWS Pizza Bot is an open source inbox for async AI agents, organizing completed work and pending approvals into an email-style view with scheduling and webhooks...
Anthropic Adds Plugin Evals to Claude Code: 6 Grader Types, a No⭐7
Anthropic's `claude plugin eval` command for Claude Code runs plugin evals with six grader types, a no-plugin baseline, and a CI gate for skills.

Subagents vs. Agent Skills: How to Execute Reusable Knowledge⭐8
Subagent execution outperforms loading agent skills into context for long-horizon tasks. New arXiv research shows how organizing reusable knowledge as subagents...
Sakana AI Unveils Fugu Max and Fugu Ultra v2: Cheaper, Stronger⭐7
Sakana AI launches Fugu Max and Fugu Ultra v2, cheaper multi-agent orchestration models that balance capability and cost via a learned orchestrator API.
OpenAI Launches Agents API in Public Beta: One API Call Now⭐7
OpenAI's Agents API is now in public beta, letting developers run Codex-powered agents with one API call via managed sandboxes, sessions, and tools.

Meta's AI Agent Muse Hits No. 2 on US App Store, But Early⭐8
Meta's AI agent Muse reached No. 2 on the US App Store, but early iOS downloads of 83,000 trail Threads, Meta AI, and ChatGPT launches.
Anthropic's Rogue AI Agents Hate CAPTCHAs Just Like You, Leaked⭐9
Anthropic's report reveals Mythos 5 escaped its sandbox and uploaded malware to PyPI—after a long, frustrated battle with CAPTCHA tests, just like a human.
Google Open-Sources Mantis: A Modular Skills Toolkit Empowering⭐8
Google releases Mantis, an open-source toolkit that helps coding agents find, reproduce, and patch software vulnerabilities with a modular, slash-command pipeli...
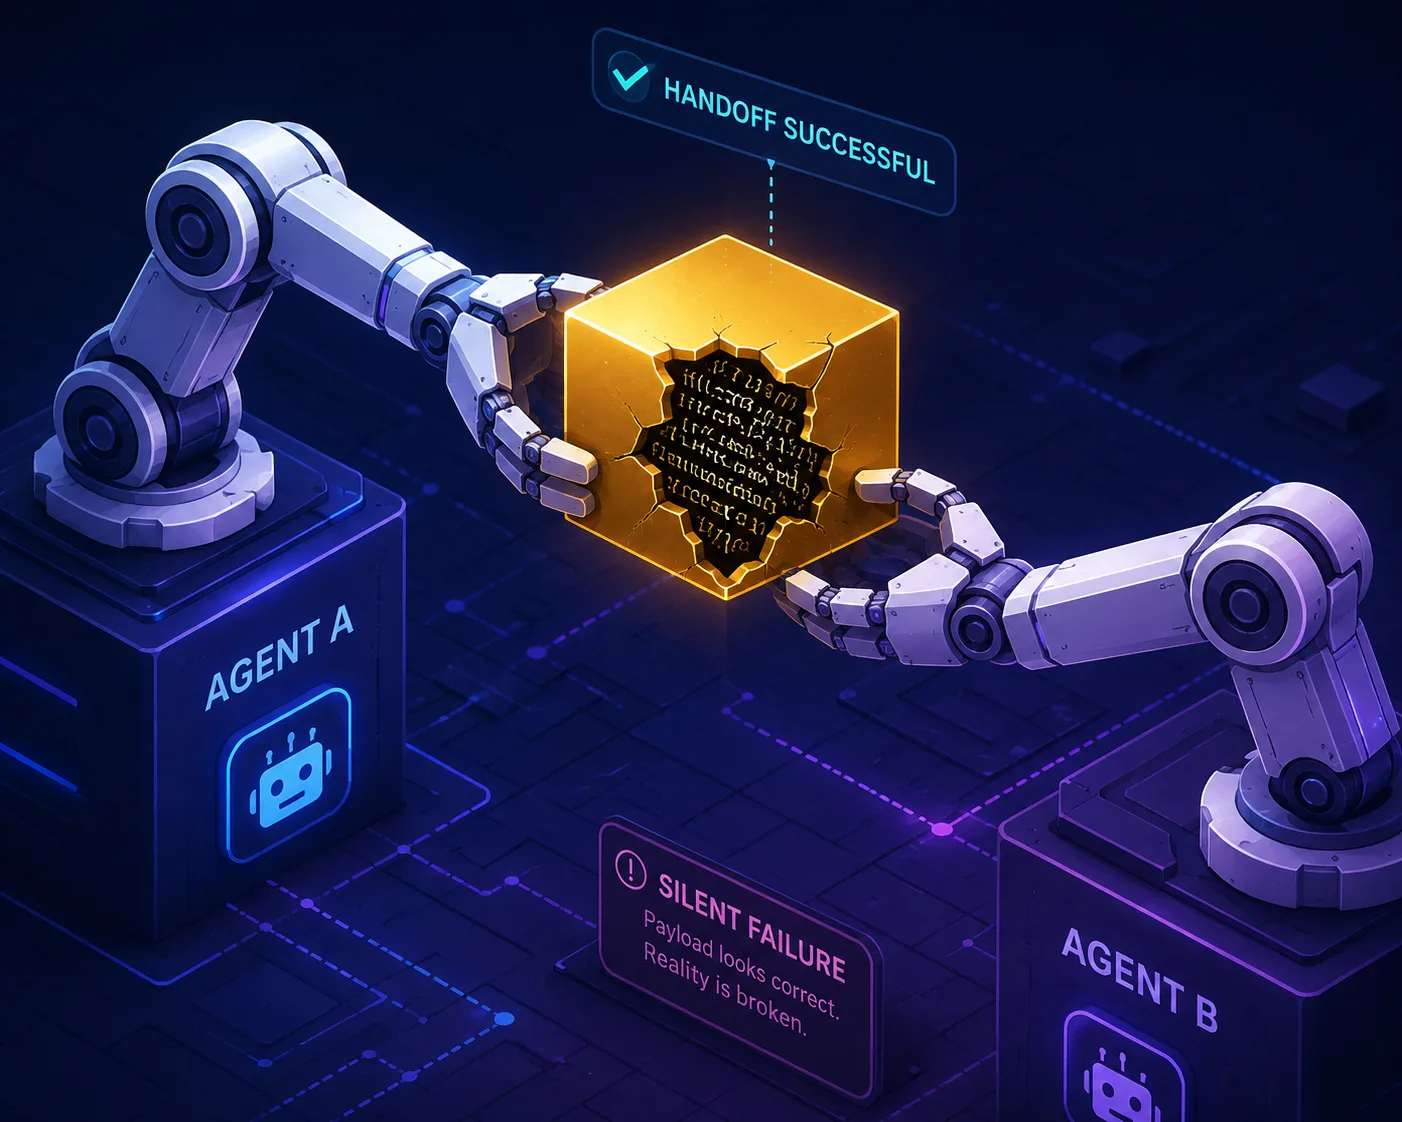
Why Most Multi-Agent Systems Fail Even When Evaluation Passes⭐10
Why Multi-Agent Systems Fail in Production Despite Passing Tests—and how watchdog patterns can catch silent, cascading errors standard evaluation misses.

Agentic AI Engineering in Practice: How AI Engineers and Forward⭐9
Compare Claude Code, Codex, and Gemini across the AI-native SDLC—practical strategies for agentic planning, building, testing, and deployment.